Tag: inference
NVIDIA Announces Jetson Orin Nano 2 for Edge AI - 2x Inference Performance, Availability Expected in H1 2027
OpenAI Publishes First Jalapeño Benchmarks: 1.5-1.9x More Work Per Watt, 1.7-3.6x Lower Latency
NVIDIA Puts the Groq 3 LPX Inference Accelerator Into Full Production - and Names the Benchmark Conditions
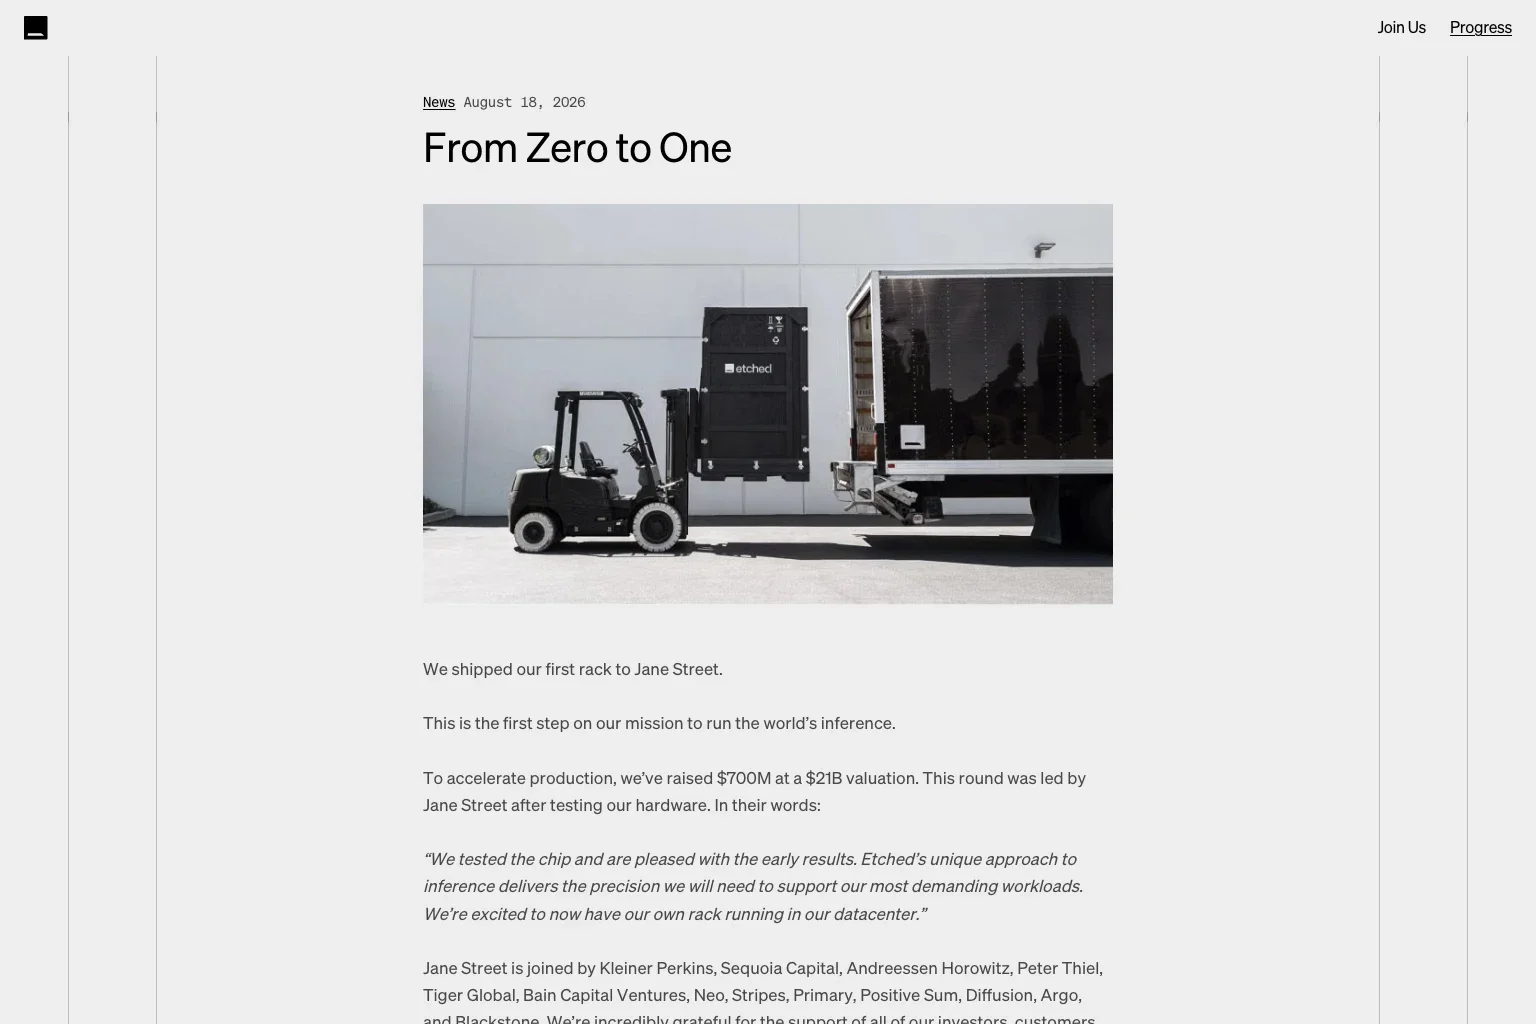
Etched Raises $700M at a $21B Valuation - First Rack Shipped to Jane Street
Groq Raises $350M Series A at $3.5B Valuation — The Money Goes to NVIDIA Clusters
OpenAI Ultrafast Mode: GPT-5.6 Sol at Up to 14x Speed, Powered by Cerebras
Mistral Regional Endpoints Go GA: Pin Inference to Europe or the US, Plus a Plan for Up to 1 GW of Compute

General Compute's $400M Loan: Inference Chips Replace GPUs as AI Collateral
